2026/10/29 更新

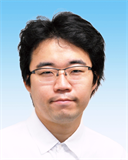
写真a

トダ コウジ
戸田 航史
TODA Koji
所属
情報工学部 情報工学科 准教授
大学院 工学研究科 修士課程 情報工学専攻 准教授
職名
准教授
連絡先
メールアドレス
外部リンク

学位

  • 博士(工学)

研究分野

  • 情報通信 / ソフトウェア

  • 情報通信 / ソフトウェア

学歴

  • 奈良先端科学技術大学院大学

  • 大阪大学

所属学協会

  • 電子情報通信学会

  • IEEE

  • 情報処理学会

委員歴

  • 情報処理学会   ソフトウェア工学研究運営委員  

    2024年4月 - 現在   

      詳細を見る

  • 日本ソフトウェア科学会   ソフトウェアの基礎ワークショップ(FOSE2024)共同実行委員長  

    2023年12月 - 現在   

      詳細を見る

  • 情報処理学会   論文誌ジャーナル編集委員  

    2022年6月 - 現在   

      詳細を見る

論文

  • プログラミング演習における細粒度編集履歴データを用いたコード流用意図の調査

    新 伊織, 戸田 航史, 井垣 宏

    実践的IT教育シンポジウム rePiT 論文集   2026 ( 0 )   11 - 20   2026年2月

     詳細を見る

    記述言語:日本語   出版者・発行元:一般社団法人 日本ソフトウェア科学会 実践的IT教育研究会  

    プログラミング演習では学生が様々な形で流用を行うことが報告されている.我々の研究グループでは,ファイル編集履歴を用いた学生によるコードの流用動向の分析を行っている.先行研究では,Java言語を対象とした学部2年生向けのある授業において,約89.2%の学生が平均3回程度の流用を行っていることや流用の大半は課題についてのコーディングをしながら同一課題内で行われていること,着手直後や完了直前の流用が多いことなどが確認された.本研究では,先行研究において特定したコード流用の中でも同一課題内における自己流用678件について著者らが目視で確認を行い,誤検出かどうか,誤検出でない場合もどのような意図によるコード流用なのかを流用行動5カテゴリ,誤検出4カテゴリに分類した.分析の結果,目視で確認を行った678件のうち流用行動は642件(約94.7%)を占め,誤検出は36件(約5.3%)であった.流用行動については,課題着手直後には機能追加を目的とした流用,エラーを解消するためなどの短期的な試行錯誤の割合が多く,中盤ではコードの位置を変更するといったものの割合が増加した.さらに,完了直前では機能追加を目的とした流用,エラーを解消するためなどの短期的な試行錯誤に加え,改善を目的としたリファクタリングによる流用などの割合が増加したことが確認された.

    DOI: 10.11309/repit.2026.0_11

    CiNii Research

  • プログラミング演習における細粒度履歴データを用いたコード流用の特定と分析

    新 伊織, 戸田 航史, 井垣 宏

    ソフトウェア工学の基礎ワークショップ論文集   32 ( 0 )   33 - 42   2025年11月

     詳細を見る

    記述言語:日本語   出版者・発行元:一般社団法人 日本ソフトウェア科学会 ソフトウェア工学の基礎研究会  

    <p>コードの流用,すなわちコードをコピーして別の箇所で再利用する行為は広く行われている.コードの流用は常に問題となるわけではない.実装の手段として良いコード片を様々なコードベースから取得することは広く行われており,最近では生成AIから出力されたコードの流用も行われている.本研究では,大学のJavaプログラミング演習における学生のソースコード流用行動を細粒度履歴データを用いて分析する.細粒度履歴データは授業中に収集された47万件を超えるコードスナップショットである.正規化およびハッシュ化を用いてスナップショット間差分からコードの流用と思われるスナップショットペアを検出する.流用元が(1)自己か他者か,(2)同一課題内か別課題か,の2軸4種類に分類し,その発生頻度や規模,時系列的な発生タイミングを詳細に調査した.分析の結果,最も頻繁に発生するのは「自己・同一課題」での流用であり,課題の初期段階や終了間際に多く見られた.また,流用されるコード行数の中央値は8行程度となっており,多くが比較的新しく作成されたものであるが,過去の課題から流用されているケースも確認された.</p>

    DOI: 10.11309/fose.32.0_33

    CiNii Research

  • The Impact of Defect (Re) Prediction on Software Testing

    Murakami Y., Yamasaki Y., Tsunoda M., Monden A., Tahir A., Bennin K.E., Toda K., Nakasai K.

    IEICE Transactions on Information and Systems   E108.D ( 3 )   175 - 179   2025年3月

     詳細を見る

    記述言語:英語   出版者・発行元:IEICE Transactions on Information and Systems  

    Cross-project defect prediction (CPDP) aims to use data from external projects as historical data may not be available from the same project. In CPDP, deciding on a particular historical project to build a training model can be difficult. To help with this decision, a Bandit Algorithm (BA) based approach has been proposed in prior research to select the most suitable learning project. However, this BA method could lead to the selection of unsuitable data during the early iteration of BA (i.e., early stage of software testing). Selecting an unsuitable model can reduce the prediction accuracy, leading to potential defect overlooking. This study aims to improve the BA method to reduce defects overlooking, especially during the early testing stages. Once all modules have been tested, modules tested in the early stage are re-predicted, and some modules are retested based on the re-prediction. To assess the impact of re-prediction and retesting, we applied five kinds of BA methods, using 8, 16, and 32 OSS projects as learning data. The results show that the newly proposed approach steadily reduced the probability of defect overlooking without degradation of prediction accuracy.

    DOI: 10.1587/transinf.2024MPL0002

    Scopus

    CiNii Research

  • Building Defect Prediction Models by Online Learning Considering Defect Overlooking

    Fedorov N., Yamasaki Y., Tsunoda M., Monden A., Tahir A., Bennin K.E., Toda K., Nakasai K.

    IEICE Transactions on Information and Systems   E108.D ( 3 )   170 - 174   2025年3月

     詳細を見る

    記述言語:英語   出版者・発行元:IEICE Transactions on Information and Systems  

    Building defect prediction models based on online learning can enhance prediction accuracy. It continuously rebuilds a new prediction model while adding new data points. However, a module predicted as “non-defective” can result in fewer test cases for such modules. Thus, a defective module can be overlooked during testing. The erroneous test results are used as learning data by online learning, which could negatively affect prediction accuracy. To suppress the negative influence, we propose to apply a method that fixes the prediction as positive during the initial stage of online learning. Additionally, we improved the method to consider the probability of defect overlooking. In our experiment, we demonstrate this negative influence on prediction accuracy and the effectiveness of our approach. The results show that our approach did not negatively affect AUC but significantly improved recall.

    DOI: 10.1587/transinf.2024MPL0001

    Scopus

    CiNii Research

  • On Applying Bandit Algorithm to Fault Localization Techniques

    Nakao M., Hamamoto K., Tsunoda M., Tahir A., Toda K., Monden A., Nakasai K., Matsumoto K.

    Proceedings 2024 IEEE 35th International Symposium on Software Reliability Engineering Workshops Issrew 2024   111 - 112   2024年

     詳細を見る

    掲載種別:研究論文(国際会議プロシーディングス)   出版者・発行元:Proceedings 2024 IEEE 35th International Symposium on Software Reliability Engineering Workshops Issrew 2024  

    Developers must select a high-performance fault localization (FL) technique from available ones. A conventional approach is to try to select only one FL technique that is expected to attain high performance before debugging activity. In contrast, we propose a new approach that dynamically selects better FL techniques during debugging activity.

    DOI: 10.1109/ISSREW63542.2024.00060

    Scopus

    researchmap

  • On the Application of Bandit Algorithm for Selecting Clone Detection Methods

    Tsunoda M., Kudo T., Monden A., Tahir A., Bennin K.E., Toda K., Nakasai K., Matsumoto K.

    IEICE Transactions on Information and Systems   advpub ( 0 )   718 - 722   2024年

     詳細を見る

    記述言語:英語   出版者・発行元:一般社団法人 電子情報通信学会  

    Various clone detection methods have been proposed, with results varying depending on the combination of the methods and hyperparameters used (i.e., configurations). To help select a suitable clone detection configuration, we propose two Bandit Algorithm (BA) based methods that can help evaluate the configurations used dynamically while using detection methods. Our analysis showed that the two proposed methods, the naïve method and BANC (BA considering Negative Cases), identified the best configurations from four used code clone detection methods with high probability.

    DOI: 10.1587/transinf.2024iil0002

    Scopus

    CiNii Research

  • Selecting Source Code Generation Tools Based on Bandit Algorithms

    Tsunoda M., Shima R., Tahir A., Bennin K.E., Monden A., Toda K., Nakasai K.

    IEICE Transactions on Information and Systems   advpub ( 0 )   723 - 726   2024年

     詳細を見る

    記述言語:英語   出版者・発行元:一般社団法人 電子情報通信学会  

    Background: Code s generation tools such as GitHub Copilot have received attention due to their performance in generating code. Generally, a prior analysis of their performance is needed to select new code-generation tools from a list of candidates. Without such analysis, there is a higher risk of selecting an ineffective tool, which would negatively affect software development productivity. Additionally, conducting prior analysis of new code generation tools is often time-consuming. Aim: To use a new code generation tool without prior analysis but with low risk, we propose to evaluate the new tools during software development (i.e., online optimization). Method: We apply the bandit algorithm (BA) approach to help select the best code suggestion or generation tool among a list of candidates. Developers evaluate whether the result of the tool is correct or not. When code generation and evaluation are repeated, the evaluation results are saved. We utilize the stored evaluation results to select the best tool based on the BA approach. In our preliminary analysis, we evaluated five tools with 164 code-generation cases using BA. Result: BA approach selected ChatGPT as the best tool as the evaluation proceeded, and during the evaluation, the average accuracy by BA approach outperformed the second-best performing tool. Our results reveal the feasibility and effectiveness of BA in assisting the selection of best-performing code suggestion or generation tools.

    DOI: 10.1587/transinf.2024iil0001

    Scopus

    CiNii Research

  • An Empirical Study of the Impact of Test Strategies on Online Optimization for Ensemble-Learning Defect Prediction

    Hamamoto K., Tsunoda M., Tahir A., Bennin K.E., Monden A., Toda K., Nakasai K., Matsumoto K.

    Proceedings 2024 IEEE International Conference on Software Maintenance and Evolution Icsme 2024   642 - 647   2024年

     詳細を見る

    出版者・発行元:Proceedings 2024 IEEE International Conference on Software Maintenance and Evolution Icsme 2024  

    Ensemble learning methods have been used to enhance the reliability of defect prediction models. However, there is an inconclusive stability of a single method attaining the highest accuracy among various software projects. This work aims to improve the performance of ensemble-learning defect prediction among such projects by helping select the highest accuracy ensemble methods. We employ bandit algorithms (BA), an online optimization method, to select the highest-accuracy ensemble method. Each software module is tested sequentially, and bandit algorithms utilize the test outcomes of the modules to evaluate the performance of the ensemble learning methods. The test strategy followed might impact the testing effort and prediction accuracy when applying online optimization. Hence, we analyzed the test order's influence on BA's performance. In our experiment, we used six popular defect prediction datasets, four ensemble learning methods such as bagging, and three test strategies such as testing positive-prediction modules first (PF). Our results show that when BA is applied with PF, the prediction accuracy improved on average, and the number of found defects increased by 7% on a minimum of five out of six datasets (although with a slight increase in the testing effort by about 4% from ordinal ensemble learning). Hence, BA with PF strategy is the most effective to attain the highest prediction accuracy using ensemble methods on various projects.

    DOI: 10.1109/ICSME58944.2024.00066

    Scopus

  • Outlier Elimination Technique Using Deletion‐Imputation Iteration for Fault‐Prone Module Detection 査読

    Koji Toda, Masateru Tsunoda

    IEEJ Transactions on Electrical and Electronic Engineering   18 ( 10 )   1653 - 1663   2023年8月

     詳細を見る

    担当区分:筆頭著者   記述言語:英語   掲載種別:研究論文(学術雑誌)  

    DOI: 10.1002/tee.23889

  • A Novel Approach to Address External Validity Issues in Fault Prediction Using Bandit Algorithms 査読

    Teruki HAYAKAWA, Masateru TSUNODA, Koji TODA, Keitaro NAKASAI, Amjed TAHIR, Kwabena Ebo BENNIN, Akito MONDEN, Kenichi MATSUMOTO

    IEICE Transactions on Information and Systems   E104.D ( 2 )   327 - 331   2021年

  • カバレッジに基づくファジングツールの比較評価 査読

    都築 夏樹, 吉田 則裕, 戸田 航史, 山本 椋太, 高田 広章

    コンピュータ ソフトウェア   37 ( 2 )   97 - 103   2020年5月

  • Capturing Spotaneous Software Evolution in a Social Coding Platform with Project-as-a-City Concept. International Journal of Software Innovation 査読

    Koji Toda, Haruaki Tamada, Masahide Nakamura, Kenichi Matsumoto

    International Journal of Software Innovation   8 ( 3 )   35 - 50   2020年

  • Evaluation of Software Fault Prediction Models Considering Faultless Cases 査読

    Yukasa Murakami, Masateru Tsunoda, Koji Toda

    IEICE Transactions on Information and Systems   E103.D ( 6 )   1319 - 1327   2020年

  • 工数予測における6種類の欠損値補完手法の実証的評価 査読

    戸田 航史, 角田雅照

    コンピュータ ソフトウェア   36 ( 4 )   95 - 106   2019年12月

  • 重回帰分析を用いた工数予測における欠損値補完手法の性能比較 査読

    戸田 航史,角田雅照

    コンピュータ ソフトウェア   34 ( 4 )   150 - 155   2017年10月

  • コードレビュー分析におけるデータクレンジングの影響調査 査読

    戸田航史, 亀井靖高, 吉田則裕

    情報処理学会論文誌,   58 ( 4 )   845 - 854   2017年4月

  • OSS開発における管理者と修正者の社会的関係を考慮した不具合修正時間予測 査読

    吉行勇人, 大平雅雄, 戸田航史

    コンピュータソフトウェア   32 ( 2 )   128 - 134   2015年4月

  • Chromiumプロジェクトにおけるレビュー・パッチ開発経験がレビューに要する時間に与える影響の分析 査読

    戸田航史, 亀井靖高, 濱崎一樹, 吉田則裕

    コンピュータソフトウェア   32 ( 1 )   227 - 233   2015年3月

  • 11種類のfault密度予測モデルの実証的評価, 電子情報通信学会 査読

    小林 寛武, 戸田 航史, 亀井 靖高, 門田 暁人, 峯 恒憲, 鵜林 尚靖

    電子情報通信学会   J96-D ( 8 )   1892 - 1902   2013年8月

  • Revisiting Software Development Effort Estimation Based on Early Phase Development Activities

    Masateru Tsunoda, Koji Toda, Kyohei Fushida, Yasutaka Kamei, Meiyappan Nagappan, and Naoyasu Ubayashi

    In Proc. of Working Conference on Mining Software Repositories (MSR 2013)   429 - 438   2013年5月

  • 重回帰分析とプロジェクト類似性を用いたハイブリッド工数見積もり方法の提案, コンピュータ ソフトウェア 査読

    戸田 航史, 角田雅照, 門田 暁人, 松本 健一

    コンピュータ ソフトウェア   30 ( 2 )   227 - 233   2013年4月

  • An Ensemble Approach of Simple Regression Models to Cross-Project Fault Prediction

    Satoshi Uchigaki, Shinji Uchida, Koji Toda, Akito Monden, Toshihiko Nakano, and Yutaka Fukuchi

    In Proc. of International Conference on Software Engineering, Artificial Intelligence, Networking and Parallel/Distributed Computing (SNPD 2012)   2012年8月

  • Automated classification of user's statement in requirement specification phase

    Koji Toda and Ken-ichi Matsumoto

    In Proc. of Joint Conference of International Workshop on Software Measurement and International Conference on Software Process and Product Measurement (IWSM/Mensura)   2011年11月

  • Fit Data Selection Based on Project Features for Software Effort Estimation Models

    Koji Toda, Akito Monden, Ken-ichi Matsumoto

    In Advances in Computer Science and Engineering (ACSE2010)   82 - 88   2010年3月

  • ソフトウェア開発工数予測のためのフィットデータ選定方法, 情報処理学会論文誌 査読

    戸田 航史, 門田 暁人, 松本 健一

    情報処理学会論文誌   50 ( 11 )   2699 - 2709   2009年11月

  • 工数予測における類似性に基づく欠損値補完法の実験的評価 査読

    田村 晃一, 柿元 健, 戸田 航史, 角田 雅照, 門田 暁人, 松本 健一, 大杉 直樹

    コンピュータ ソフトウェア   26 ( 3 )   44 - 55   2009年8月

  • Empirical Evaluation of Missing Data Techniques for Effort Estimation

    Koichi Tamura, Takeshi Kakimoto, Koji Toda, Masateru Tsunoda, Akito Monden, and Ken-ichi Matsumoto

    In Proc. of International Workshop on Software Productivity Analysis And Cost Estimation (SPACE2008)   4 - 9   2008年12月

  • Fit Data Selection for Software Effort Estimation Models

    Koji Toda, Akito Monden, and Ken-ichi Matsumoto

    In Proc. of the 2nd international symposium on Empirical software engineering and measurement (ESEM'08)   360 - 361   2008年10月

  • プロジェクト類似性に基づく工数見積もりに適した変数選択法 査読

    瀧 進也, 戸田 航史, 門田 暁人, 柿元 健, 角田 雅照, 大杉 直樹, 松本 健一

    情報処理学会論文誌   49 ( 7 )   2338 - 2348   2008年7月

  • 上流工程での活動実績を用いたソフトウェア開発工数見積もり方法の定量的評価 査読

    角田 雅照, 戸田 航史, 伏田 享平, 亀井 靖高, 鵜林 尚靖

    コンピュータ ソフトウェア   31 ( 2 )   129 - 143  

▼全件表示

MISC

講演・口頭発表等

  • プログラミング演習における細粒度履歴データを用いたコード流用の分析

    新 伊織, 戸田 航史, 井垣 宏

    ソフトウェアエンジニアリングシンポジウム2025  2025年9月 

     詳細を見る

    開催年月日: 2025年9月

    記述言語:日本語  

    researchmap

共同研究・競争的資金等の研究課題

  • ファジングが発見した不具合の自動修正技術

    研究課題/領域番号:24K02923  2024年4月 - 2028年3月

    日本学術振興会  科学研究費助成事業  基盤研究(B)

      詳細を見る

    担当区分:研究分担者  資金種別:競争的資金

    配分額:18330000円 ( 直接経費:14100000円 、 間接経費:4230000円 )

  • 自発的ソフトウェア進化の加速に向けた基礎技術の開発

    研究課題/領域番号:17H00731  2017年4月 - 2020年3月

    日本学術振興会  科学研究費助成事業  基盤研究(A)

      詳細を見る

    担当区分:研究分担者  資金種別:競争的資金

    配分額:44850000円 ( 直接経費:34500000円 、 間接経費:10350000円 )

担当授業科目(学内)

  • 2025年度   コンピュータアーキテクチャⅠ

  • 2025年度   確率統計論

  • 2025年度   情報基礎ゼミナール

  • 2025年度   プロジェクト型演習Ⅰ

  • 2025年度   システム工学とプロジェクト管理

  • 2025年度   プロジェクト型演習Ⅱ

  • 2025年度   情報工学実験Ⅲ

  • 2025年度   情報工学特別講義

  • 2025年度   卒業研究

  • 2025年度   知能情報工学演習Ⅰ

  • 2025年度   知能情報工学特別研究

  • 2024年度   コンピュータアーキテクチャⅠ

  • 2024年度   確率統計論

  • 2024年度   情報基礎ゼミナール

  • 2024年度   プロジェクト型演習Ⅰ

  • 2024年度   プロジェクト型演習Ⅱ

  • 2024年度   情報工学実験Ⅲ

  • 2024年度   情報工学特別講義

  • 2024年度   卒業研究

  • 2024年度   知能情報工学演習Ⅰ

  • 2023年度   コンピュータアーキテクチャⅠ

  • 2023年度   確率統計論

  • 2023年度   情報基礎ゼミナール

  • 2023年度   プロジェクト型演習Ⅰ

  • 2023年度   プロジェクト型演習Ⅱ

  • 2023年度   情報工学実験Ⅲ

  • 2023年度   卒業研究

  • 2023年度   知能情報工学演習Ⅰ

  • 2022年度   情報基礎ゼミナール

  • 2022年度   コンピュータアーキテクチャⅠ

  • 2022年度   プロジェクト型演習Ⅰ

  • 2022年度   確率統計論

  • 2022年度   情報工学実験Ⅲ

  • 2022年度   情報工学特別講義

  • 2022年度   卒業研究

  • 2022年度   知能情報工学演習Ⅰ

  • 2021年度   情報基礎ゼミナール

  • 2021年度   確率統計論

  • 2021年度   プロジェクト型演習Ⅰ

  • 2021年度   コンピュータアーキテクチャⅡ

  • 2021年度   プロジェクト型演習Ⅱ

  • 2021年度   情報工学実験Ⅳ

  • 2021年度   情報工学特別講義

  • 2021年度   卒業研究

  • 2021年度   知能情報工学演習Ⅰ

  • 2020年度   情報基礎ゼミナール

  • 2020年度   プロジェクト型演習Ⅰ

  • 2020年度   確率統計論

  • 2020年度   コンピュータアーキテクチャⅡ

  • 2020年度   情報工学実験Ⅳ

  • 2020年度   情報工学特別講義

  • 2020年度   卒業研究

  • 2020年度   知能情報工学演習Ⅰ

  • 2019年度   情報基礎ゼミナール

  • 2019年度   コンピュータアーキテクチャⅡ

  • 2019年度   プロジェクト型演習Ⅰ

  • 2019年度   確率統計論

  • 2019年度   情報工学実験Ⅳ

  • 2019年度   情報工学特別講義

  • 2019年度   卒業研究

  • 2019年度   知能情報工学演習Ⅰ

  • 2018年度   情報基礎ゼミナール

  • 2018年度   コンピュータアーキテクチャⅠ

  • 2018年度   コンピュータ科学

  • 2018年度   プロジェクト型演習Ⅰ

  • 2018年度   確率統計論

  • 2018年度   プロジェクト型演習Ⅱ

  • 2018年度   英語プレゼンテーション

  • 2018年度   情報工学実験Ⅳ

  • 2018年度   卒業研究

  • 2018年度   知能情報工学演習Ⅰ

  • 2017年度   コンピュータ科学

  • 2017年度   情報基礎ゼミナール

  • 2017年度   コンピュータアーキテクチャⅠ

  • 2017年度   プロジェクト型演習Ⅰ

  • 2017年度   確率統計論

  • 2017年度   情報工学実験IV

  • 2017年度   情報工学特別講義

  • 2017年度   卒業研究

  • 2016年度   コンピュータアーキテクチャⅠ

  • 2016年度   情報基礎ゼミナール

  • 2016年度   オートマトンと形式言語

  • 2016年度   確率統計論

  • 2016年度   情報工学実験IV

  • 2016年度   情報工学特別講義

  • 2016年度   英語プレゼンテーション

  • 2016年度   卒業研究

▼全件表示